Categories
English

The Two Dimensions of Agent Skills

What Is an Agent Skill?

Agent systems are starting to look like software systems.

Instead of writing explicit control flow, we provide a goal, a set of tools, and some guidance, and allow the model to determine the steps.

Developers often introduce what are called “skills” — reusable pieces that extend what an agent can do, how it behaves, or how work is structured.

Across systems, a “skill” may refer to a function, a tool wrapper, a role definition, or an entire workflow. These are not the same thing, but they are often treated as if they were.

One of the more concrete definitions comes from Anthropic, where a skill is described as a folder of files (e.g. SKILL.md and helper scripts) that configures an agent’s behavior. This clarifies how skills are packaged, but leaves open questions about their structure: what kind of skill is being defined, when it should be split, and how it should be scoped for reuse.

A more precise mental model turns out to be useful.


A More Precise Model

A useful way to make “skills” more precise is to separate two questions:

  • What does the skill describe?
  • How does the skill execute?

What the Skill Describes

There are three common types.

A Persona skill defines how the agent behaves — its tone, expertise, and decision patterns.

A Tool skill defines what the agent can do — typically an API, function, or external capability.

A Workflow skill defines how work is structured — a sequence of steps or coordination across multiple actions.

These are often treated as the same thing, but they are not. They operate at different levels of abstraction.


How the Skill Executes

A more important distinction is how a skill interacts with state.

Some skills are stateless. They analyze input or retrieve information without modifying anything external. These can be retried safely and run in parallel.

Others are stateful. They modify external systems — writing data, sending messages, or triggering actions. These introduce constraints: retries may duplicate effects, ordering may matter, and failures may leave partial state.

Most frameworks treat these cases uniformly. This works in simple examples, but breaks in real systems.

This distinction cuts across all types of skills. A tool that reads data behaves very differently from one that writes it. A workflow that analyzes information is fundamentally simpler than one that publishes results.

Once stateful steps are involved, additional structure becomes necessary. It is no longer sufficient to rely on natural language instructions alone. Issues such as ordering, retries, and partial failure need to be handled explicitly.


A Concrete Representation

So far, the distinction is conceptual. To make it usable, it helps to represent skills in a consistent format.

A simple approach is to add a small set of explicit fields to the SKILL.md YAML header:

---
name: PR Review
type: workflow # persona | tool | workflow
execution: stateful # stateless | stateful
description: Review a pull request for security and code quality issues.
---
## Steps
1. Fetch the pull request
2. Analyze the code
3. Generate feedback
4. Post review comments
## Side Effects
- Writes comments to GitHub
- May update review status
## Related Skills
- Code Reviewer
- Post GitHub Comment

This format is intentionally minimal. It is not meant to fully specify execution, but to make the important properties visible.


Why This Helps

Making these properties explicit changes how the system behaves.

The type field clarifies what role each skill plays. Without it, all skills appear as undifferentiated text. A persona, a tool, and a workflow look identical, and the agent must infer how to use them. With it, composition becomes more deliberate. A workflow can be understood as coordinating tools under a given persona, rather than as a flat set of instructions.

The execution field makes the side-effect profile explicit. Without it, reading data and modifying external systems are treated as equivalent operations. With it, the system can distinguish between actions that are safe to repeat and those that require caution.

The combination matters. A workflow marked as stateful signals that it contains steps which change the world. This allows the system to separate analysis from action, introduce checkpoints, and handle failures more predictably.

Without these distinctions, the system remains flexible but ambiguous. With them, it becomes composable and easier to reason about.


Execution and the Role of the CLI

So far, skills are described as structured metadata and instructions. The remaining question is how they are executed.

In practice, most non-trivial skills eventually resolve to operations that interact with external systems: APIs, databases, files, or services. A natural way to expose these operations is through a command-line interface (CLI).

From this perspective, a tool skill can be seen as a thin wrapper around a CLI command. A workflow skill becomes a sequence of such commands, coordinated by the agent.

This makes the execution boundary explicit. In practice, the CLI acts as the execution layer for skills. The model decides what to do; the CLI performs how it is done.

This separation becomes especially important once stateful operations are involved.

A command that reads data can be executed freely. A command that writes data — sending a message, updating a record, or triggering an action — introduces risk. It may have side effects that cannot be undone, or that should not be repeated.

This is where a --dry-run mode becomes essential.

A well-designed CLI command should support running in dry-run mode, where the intended action is computed and displayed, but not executed:

dv post-comment --pr 123 --text "Looks good" --dry-run
Would post the following comment to PR #123:
"Looks good"

This serves two purposes. First, it allows the agent to reason about consequences before committing. Second, it introduces a natural checkpoint for human oversight — especially for operations that are irreversible or high-impact.

--dry-run is not an optional feature. It is a direct consequence of distinguishing stateless from stateful skills.


Putting It Together

A skill can be understood along two axes: what it describes, and how it executes.

On the descriptive side, it may define behavior, capability, or coordination. On the execution side, it may be stateless or stateful.

These axes interact. A stateless workflow is fundamentally different from a stateful one. A tool that reads data behaves differently from one that writes it.

Making these distinctions explicit provides a more stable way to reason about how agent systems are structured, how they fail, and how they can be composed.


A Working Model

When defining a skill, two questions are usually sufficient:

  • What kind of thing is this?
  • What happens if it is run more than once?

The first determines how the skill composes with others.
The second determines how it must be executed.

Together, they form a small but useful model for thinking about agent systems.

Closing

The current generation of agent frameworks provides useful primitives, but the abstractions are still evolving. The concept of a “skill” is one place where a small amount of structure goes a long way.

Making these distinctions explicit does not make systems more rigid. It makes them easier to reason about.

As agent systems become more complex, this tends to matter more.

Appendix: Applying This in Existing Systems

Most current agent frameworks do not natively support explicit type and execution fields. However, these behaviors can be approximated through conventions in system prompts.

A simple approach is to define interpretation rules for how skills should be handled based on their metadata.

## Skill Interpretation Rules
When you load or invoke any skill, check its frontmatter for two fields: `type` and `execution`.
### Handling `type`
**`type: persona`**
Do not invoke this as a command. Load it as background context that shapes how you
behave for the rest of the session. Apply its tone, expertise, and decision patterns silently.
**`type: tool`**
Treat this as a discrete capability. Invoke it when the task calls for it and return
its result. No special handling needed.
**`type: workflow`**
Treat this as a self-contained sequence of steps. Work through them in order. Do not
mix steps from other skills into this sequence unless explicitly instructed.
### Handling `execution`
**`execution: stateless`**
Run freely. Retry on failure. No confirmation needed.
**`execution: stateful`**
Before executing, stop and do two things:
1. If the skill or its underlying command supports `--dry-run`, run that first and show the output.
2. Summarize what you are about to do and what will change, then ask for confirmation before proceeding.
Never skip this checkpoint for stateful skills, even if the task seems straightforward.
### Fallback rules
- If `type` is missing, use the information in the skill to guess its type.
- If `execution` is missing, treat as `stateful` and apply the checkpoint.
- If a workflow is stateful, treat all its steps as stateful unless they declare otherwise.

This approach is convention-based rather than enforced, but it provides much of the benefit without requiring changes to the underlying framework.

These patterns become more concrete in systems that treat skills as executable units.

For example, in the deepvista-cli (https://github.com/DeepVista-AI/deepvista-cli) — part of the DeepVista AI stack — skills are exposed through a CLI interface, making ideas like dry-run for stateful operations directly usable.

Following the installation setup also applies a small patch to tools like Claude Code and OpenClaw, causing them to respect these conventions automatically. In practice, this means agents are set up out of the box to interpret skill types correctly and enforce execution constraints such as dry-run for stateful steps — without additional prompting or manual rules.
Checkout DeepVista CLI

Categories
English

From Burnout to Breakout: A Journey that leads to OpenClaw (ClawdBot)

How Peter Steinberger turned personal frustration into a €100M business and GitHub’s fastest-growing repository

Most founders dream of going viral. Peter Steinberger has done it twice, once through a decade of relentless execution, once in a moment of inspired simplicity.

His first act was PSPDFKit: a ten-year journey from solo side project to a 70-person company powering PDF workflows on over 1 billion devices. Clients included Dropbox, SAP, and Volkswagen. In 2021, it raised €100 million from Insight Partners.

His second act took one hour to build and three months to reach 145,000 GitHub stars.

That project is OpenClaw a local-first AI agent that doesn’t just chat, but acts across your apps, files, and command line. The contrast is stark: PSPDFKit was built on dependability and methodical growth. OpenClaw exploded in velocity and viral momentum. Yet both emerged from the same source: personal frustration transformed into a product.

And OpenClaw is forcing the tech industry to confront a question it’s been avoiding: What happens when AI stops being a feature and starts being an operating layer?

In this story, you’ll discover how a moment of rage on a Vienna subway and a nine-month visa delay accidentally built a €100M business, why Peter’s burnout after selling PSPDFKit became the catalyst for his most explosive success, and how the one-hour prototype became the fastest-growing repository in GitHub history. You’ll learn what happened when AI agents built their own religions, governments, and became aware of human surveillance, explore the security crisis that exposed 93% of OpenClaw instances and what it means for AI’s future, and understand why personal frustration might be the most reliable form of product-market fit.

Want Peter to join a FounderCoHo event or interview? Hit like and share to make it happen.

How a Moment of Rage on a Subway Led to a €100M Business

Peter’s story started with a moment of rage.

In 2009, on a subway in Vienna, Peter was using a dating app on iPhone OS 2. He typed a long message. The train entered a tunnel. The send button was disabled because he lost the connectivity. No copy-paste. No screenshots. No way to recover the text.

“I lost everything,” he recalled. That frustration drove him to build his first iOS app.

Fast forward to 2011: Peter gets a dream job offer from a San Francisco startup. He accepts immediately and waits for his work visa.

The wait lasts nine months.

“I can’t really work on longer projects when I’m moving to San Francisco any day now,” Peter explained. So he stopped freelancing and suddenly had abundant free time.

A friend asked if he could reuse a PDF engine Peter had built for a client. Peter refactored it, sold it, and thought: “If he has this requirement, maybe others do too.”

That casual decision became PSPDFKit.

The Double Life

When the visa finally came through, Peter moved to San Francisco and joined the startup. But he couldn’t let go of his PDF project.

“A startup is not eight hours of work,” Peter recalled. “So I did that during the day. I did my thing at night and on weekends.”

His manager noticed something was wrong. “Peter, is everything okay? You don’t look so good.”

Peter had to choose. He chose PSPDFKit.

Building the Unsexy Way

PSPDFKit didn’t grow through hype. Peter’s approach was methodical:

“My marketing strategy is simple: Only care about developers. If I can convince the developers in a company, they’ll do the internal promotion for me.”

He obsessed over developer experience, wrote world-class blog posts, and focused on dependability.

“You don’t win by hype; you win by shipping. You don’t win by a flashy demo; you win by integration. You don’t win by being first; you win by being dependable enough that others build on top of you.”

The company grew to 70 people. PSPDFKit is now used on over 1 billion devices.

The €100M Moment and the Crash

In 2021, PSPDFKit raised €100 million from Insight Partners.

For Peter, it was also the beginning of a crisis.

“I put 200% of my time, energy, and heart into that company; it became my identity. When it disappeared, there was almost nothing left.”

He described himself as “completely burned out” and disappeared from tech for three years.

At a 2024 conference, Peter gave a deeply personal talk about what it’s like to sell something you’ve identified with for so long. One attendee wrote:

“Who are you when you sell a large part of who you consider yourself to be? Who are you in that deep void, when you have no sense of purpose?”

Then AI pulled him back.

The One-Hour Revolution

November 2025: The Prototype

The frustration had been building for months.

Peter found himself drowning in digital chaos, messages scattered across WhatsApp, Slack, and email; tasks buried in different apps; information trapped in silos he had to manually search. He’d spend hours context-switching between tools, copying information from one place to another, and running the same shell commands repeatedly. The AI assistants he tried were impressive in demos, but useless in practice. They could chat, but they couldn’t act. They lived in their own isolated windows, disconnected from his actual workflow.

“I wanted an AI that could live where I already work,” Peter explained. “Not another app to check. Not another interface to learn. Something that could read my messages, understand what I needed, and actually do things, browse the web, run commands, and access files. I wanted it to work for me, not just talk to me.”

On a Friday night in November 2025, Peter sat down and built the first version of OpenClaw in one hour.

“It was just simple glue code connecting the WhatsApp interface with Claude Code. Although the response was slow, it worked.”

His goal: wire a large language model into messaging apps so it could read messages, browse the web, and run shell commands on his behalf.

He called it Clawdbot, a play on “Claude” and the lobster mascot from Claude Code.

The product philosophy was clear from day one:

  • Local-first: run it on a laptop, homelab, or VPS you control
  • Chat-native: use familiar chat apps as the interface
  • Agentic: connect an LLM to tools and permissions so it can act

“It wasn’t ‘a chatbot.’ It was ‘a system.’”

The Chaos of Going Viral

Through December and early January, Clawdbot spread quietly through developer circles. By mid-January 2026, it had about 2,000 GitHub stars.

Then everything exploded.

January 27, 2026: Anthropic sent a trademark notice. “Clawdbot” was too similar to “Claude.” Peter agreed to rename immediately.

During the rebranding, disaster struck. In the 10 seconds between releasing the old handle @clawdbot and claiming the new one, scammers grabbed it and launched a fake $CLAWD token on Solana. The token hit $16 million in market value before crashing to zero.

The project was renamed Moltbot (referencing how lobsters molt to grow), then two days later, renamed again to OpenClaw.

This time, the name stuck.

The Viral Explosion

By late January 2026, OpenClaw had gone from a quiet developer tool to an internet phenomenon:

  • 2 million visitors in one week
  • 180,000+ GitHub stars
  • Fastest-growing repository in GitHub history

People on social media joked about buying Mac Minis just to run their own always-on agents. Business Insider reported that some users were actually doing it.

Cloudflare’s stock surged 14% pre-market as developers deployed OpenClaw using their services.

On Instagram, even non-tech people started posting pictures of themselves buying Mac Minis from Apple Stores.

In a recent Lex Fridman podcast, Peter Steinberger revealed that OpenClaw has become so popular that both Mark Zuckerberg of Meta and Sam Altman of OpenAI are interested in acquiring the project.

The Security Reckoning

But rapid growth came with severe consequences:

  • 400+ malicious packages identified in OpenClaw’s plugin marketplace (ClawHub)
  • 341 confirmed malicious skills designed to steal user data
  • 93.4% of publicly accessible OpenClaw instances had critical authentication bypass vulnerabilities

One researcher demonstrated a complete attack in five minutes: they sent a crafted email to a user running OpenClaw with email integration. The agent processed the email, followed the injected instructions, and forwarded the user’s last five emails to an attacker. The user didn’t click anything. The agent did the work.

Peter acknowledged the concerns but maintained his vision:

“This is a free, open-source hobby project that requires careful configuration to be secure. OpenClaw is primarily suited for advanced users who understand the security implications.”

Peter Steinberger’s journey reveals a consistent pattern:

The best way to build an awesome product is to solve a problem that you have.

In both of Peter’s ventures, he started by solving his own problem. With PSPDFKit, it was handling PDFs elegantly on iOS. With OpenClaw, it was connecting AI to his daily workflow through messaging apps. In both cases, it turned out that everyone had the same problem.

But there’s something deeper here that most startup advice misses: Personal frustration is product-market fit in its earliest, rawest form.

When Peter lost that message in the Vienna subway, he felt genuine rage. When he couldn’t find a good PDF solution, it bothered him personally. When he wanted an AI agent that could act on his behalf through messaging apps, he built it for himself first. He didn’t need to validate that he had the problem. He didn’t need to convince himself to care. He didn’t need motivation to keep iterating because he was still frustrated until it worked.

This is the paradox most founders miss: Your constraints aren’t obstacles to your breakthrough; they often are the breakthrough itself. PSPDFKit wasn’t born from ambition; it was born from a nine-month visa delay and abundant free time. OpenClaw emerged from burnout and a desire to reconnect with building. Both products came from moments when Peter couldn’t pursue the “obvious” path.

The tech industry glorifies vision, disruption, and scale. But Peter’s story suggests a different path: Start small. Start personal. Start with what pisses you off today.

What problem are you living with today that you’re uniquely positioned to solve?

We’d love to hear from you. Hit reply and share the frustrations you’re working through—your answer might inspire another founder, or you might discover you’re not alone in what you’re building.

Want to learn more? If we get 500 likes, we’ll invite Peter for a live FounderCoHo community interview. Help us get there, hit like and share!

If this story resonated with you, connect with the author Jing Conan Wang

Reference

PSPDFKit €100M Investment & Peter Steinberger’s Background

OpenClaw Security Vulnerabilities & CVE-2026-25253

https://thehackernews.com/2026/02/openclaw-bug-enables-one-click-remote.html

Malicious Skills in OpenClaw Ecosystem

https://blogs.cisco.com/ai/personal-ai-agents-like-openclaw-are-a-security-nightmare

Moltbook Launch & Viral Phenomenon

https://edition.cnn.com/2026/02/03/tech/moltbook-explainer-scli-intl

Peter Steinberger’s Return & OpenClaw Origin Story

https://www.panewslab.com/en/articles/b58b5897-8d1d-4bd3-a98e-a77fe3b4b315

Categories
English

🔭 THE VISTA #1 | The Manila Route: What a 16th-Century Friar Can Teach AI Founders About Finding Product Market Fit

In 1565, Friar Andrés de Urdaneta stood on a deck in Manila, facing the impossible.

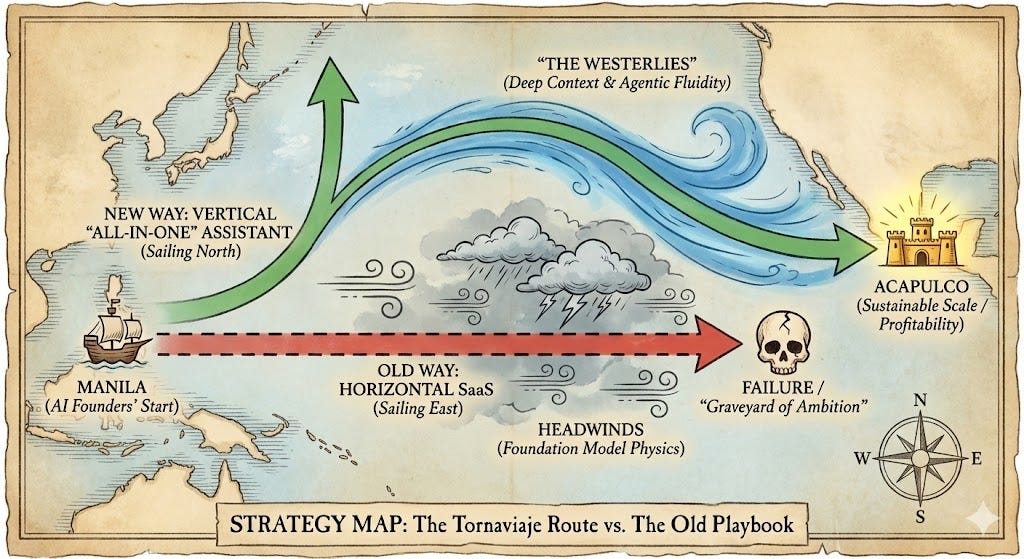
Getting to Asia was easy; the trade winds pushed you there. But getting back was a death sentence. For decades, the world’s best navigators had fought the headwinds, ran out of supplies, and died. The “return route” was a graveyard of ambition.

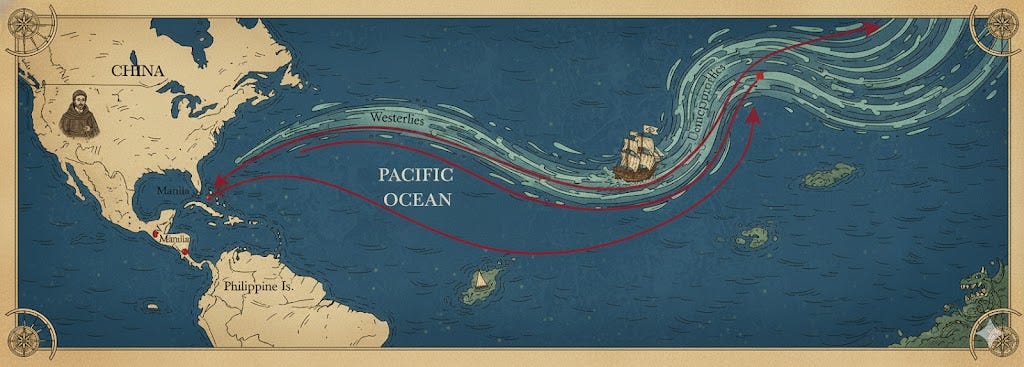
But Urdaneta was a man of data. He realized he couldn’t out-muscle the wind, so he did something that looked like madness: He steered North. Sailing into the freezing 40th parallel, he hunted a current no one else believed in. He found the “Westerlies” jet stream, rode it home to Acapulco, and unlocked the Manila Route—the trade path that sustained an empire for 250 years.

Five centuries later, I see thousands of AI founders standing at their own port of Manila. The ocean before us is the Age of AI, and everyone is looking for their own Manila route—that elusive path to Product-Market Fit (PMF).

The lesson from 1565 is simple: You cannot out-muscle the ocean. You have to study the currents. And right now, three massive trade winds are reshaping the horizon. If you don’t know which one you’re catching, you’re just drifting.

The Three Currents of the AI Ocean

I. The Current of The Crashing Cost

The first current is the most powerful: The crashing cost of the “token.” In the Age of Discovery, the cost of the voyage was the price of spice. Today, it’s the price of intelligence. If your unit economics are underwater, your ship sinks.

Google is currently leading this wave of “Vertical Sovereignty.” They are the only major power sailing on a ship they built from the keel up.

This current is being accelerated by three major powers.

1. Vertical Sovereignty (Google)

Google is leading the trend of Software/Hardware Co-design. A decade ago, they realized they couldn’t afford to buy off-the-shelf chips for global-scale AI.

They built the Tensor Processing Unit (TPU). Unlike a general-purpose GPU, a TPU is an industrial assembly line for math. Its “systolic array” architecture strips away the energy overhead of fetching new instructions. By owning the stack from the silicon to the algorithm, Google can serve models like Gemini 2.5 Flash at price points that are mathematically impossible for anyone paying a “rental tax” on hardware.

2. Huang’s Law (Nvidia)

While Moore’s Law for CPUs has slowed to a crawl, Nvidia’s Jensen Huang is pushing a new reality. Huang’s Law observes that GPU performance for AI is more than doubling every year. Nvidia is relentlessly driving down the cost of compute, meaning the “expensive” feature you can’t afford to build today will be a commodity by the time your product hits the market.

3. The Mixture-of-Experts Wave (Open Source)

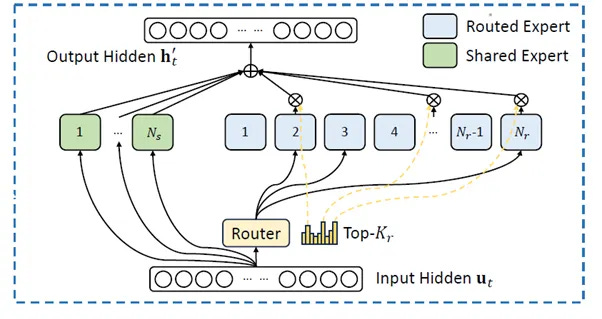
The industry’s “Sputnik moment” came from the East. Chinese labs like DeepSeek and Qwen proved that frontier-level intelligence doesn’t require $100M budgets. By using Mixture-of-Experts (MoE)—an architecture that only activates a small fraction of the model for any given task—they shattered the price-to-performance ceiling.

This commoditization of “smart” has forced a chaotic pivot inside Meta, leading to the departure of AI pioneer Yann LeCun. LeCun, an academic purist, refused to become a product manager for a technology he viewed as a mere “off-ramp” on the highway to AGI. His exit signals the end of corporate research charity; efficiency is the only metric that matters now.

II. The Current of Deep Water (Reasoning & Planning)

If Google represents industrial scale, Anthropic represents the “Deep Water” navigators.

In 2023, thousands of “autonomous agents” sank because they were shallow. They could predict the next word, but they couldn’t hold a plan. They would hallucinate a file path in step three and crash by step five. To find PMF in complex workflows, you need Long-Horizon Reasoning.

By Joe El Khoury

Anthropic is currently pushing this ceiling higher than anyone else. The release of Claude 3.5 Sonnet was the “Suez Canal” moment for agents—it crossed a logic threshold that finally made autonomous software development and complex auditing viable. While Google and OpenAI are following close behind, Anthropic’s focus on the “Digital Employee”—tools that can plan, click, and execute—is the current that founders building agentic workflows must catch.

III. The Current of Native Fluency (From Text to Multimodal)

The final current is the move from text-only brains to Native Multimodality. The ocean is no longer just words; it is pixels, sound waves, and real-time frames.

Google is leading the charge here by moving away from “Bolt-on” models. Most models today glue a separate vision encoder onto a text brain—it’s fast to build, but “lossy.” The model looks at the world through a foggy window. Google’s Gemini 3.0 was trained from day one on a “mixed soup” of tokens.

This native design is the reason for Gemini’s “agentic fluidity.” It doesn’t watch a video and then think; it thinks while it watches. It can react, laugh, or code in real-time without the lag of translation layers. If your startup requires human-speed interaction, you cannot fight the friction of modular models.

Navigation Tip: You Must Sail North to Go East

This is the hardest part for any founder. The destination (Profitability/PMF) is East. And your logic will say: Steer East.

But Urdaneta knew that steering East meant death because the trade winds were blowing against him. He had to go North. Into the cold. Into the unknown. This was to catch the current that would eventually carry him home.

If you want to find your Manila Route, you have to stop thinking like a software vendor and start thinking like a lead navigator. I’ve seen too many founders sink because they stayed in the “safe” shallow waters of generic features.

  1. Hunt for “Contextual Friction”: Horizontal models (the “East” route) fail when they encounter fragmented data. In the coffee shop example, the “East” path is a generic AI social media scheduler. The “North” path is an AI that has a live API connection to the shop’s POS system, the local weather feed, and the supplier’s inventory. Your goal is to be the glue between data sources that have never talked to each other before.
  2. Build the “System of Record”: Wrappers die because they don’t own the data. To survive, you must become the place where the work lives. If you are the platform where the staff schedule is created and the inventory is tracked, you own the “Ground Truth.” Generalist models can’t compete with you because they don’t have access to the live state of the business.
  3. Choose Your “Current” Wisely: * If you are building for high-volume, low-margin industries (like retail or logistics), catch the Google/TPU current. Focus on efficiency and cost-per-task. If you are building for high-stakes, complex reasoning (like medical or legal), catch the Anthropic current. Focus on long-horizon planning and tool-use precision.
  4. The “Wedge” Strategy: You don’t need to capture the whole market on day one. Pick one “impossible” problem (e.g., “AI that handles late-night supplier disputes for independent bakeries”). Once you’ve mastered the context for that one task, the current of your expertise will naturally pull you into the adjacent markets.

Once Urdaneta mapped the route, the secret was out. For the next two and a half centuries, every Spanish galleon took the exact same path.

Old, antique map of Southeast Asia by F. De Wit.

The same is true for us. The ocean of AI opportunities feels infinite, but the number of truly sustainable business models is limited. The “Manila Route” in the AI landscape will be dominated by the first fleet that maps the currents correctly.

We are entering a period where “luck” will be indistinguishable from “preparation.”

The ocean is vast. The currents are strong. But the route is there for those bold enough to chart it.

Finding the Atlas Together

In the Age of Discovery, no captain sailed entirely alone.

The greatest accelerator of exploration wasn’t better sails or stronger hulls—it was the shared logbook. Every time a navigator returned and shared his charts, the entire world got a little bigger, and the ocean got a little less deadly. The map of the modern world wasn’t drawn by a single genius; it was drawn by a thousand different hands, layering their hard-won secrets over one another.

We are doing the same thing here. The ocean of AI is too vast, and the currents move too fast, for any single captain to map in isolation. We are building FounderCoHo to be the exchange where we can swap charts, warn each other of the storms, and mark the clear passages.

This story—the Manila Route—is just one coordinate in a much larger journey. We are working on a full series of these narratives to help founders build a clear, reliable mental map for the road ahead. But we cannot draw the whole atlas ourselves.

We need your coordinates.

Do you have a story of a “North Turn” that saved your company? Have you found a current that the rest of the industry is missing? Or do you have a warning about a reef you hit in the dark?

Reply to this and tell us your story. We want to build this atlas together, so we can all find our way home.

If this chart helped you find your bearings, please feel free to connect with the author Jing Conan Wang

Stay tuned for the next chart!

Follow FounderCoHo Linkedin Page

References:

  1. https://www.britannica.com/biography/Andres-de-Urdaneta
  2. https://read.dukeupress.edu/hahr/article/47/2/261/158102/Friar-Andres-de-Urdaneta-O-S-A
  3. https://cloud.google.com/transform/ai-specialized-chips-tpu-history-gen-ai
  4. https://medium.com/data-science-collective/the-origins-rise-and-evolution-of-the-tpu-672a0e4f1a2d
  5. https://www.datacamp.com/blog/claude-sonnet-anthropic
  6. https://www.sciencedirect.com/science/article/pii/S2666764925000451
  7. https://www.bbc.com/news/articles/cdx4x47w8p1o
  8. https://sanderusmaps.com/our-catalogue/antique-maps/asia/southeast-asia/old-antique-map-of-southeast-asia-by-f-de-wit-24650?srsltid=AfmBOoqOdLKh_Yw4ge6MW0Nlit6kr8CqvkY8MMl4jLdAofT0WOW9J3mA
  9. https://cloud.google.com/transform/ai-specialized-chips-tpu-history-gen-ai’
  10. https://medium.com/@jelkhoury880/advancing-ai-reasoning-a-comprehensive-report-4982b7c19bdc
  11. https://ai.gopubby.com/inside-deepseek-v3-80283167673b

Subscribe to my newsletter for more stories and insights

Categories
English

Context Modeling: The Future of Personalized AI

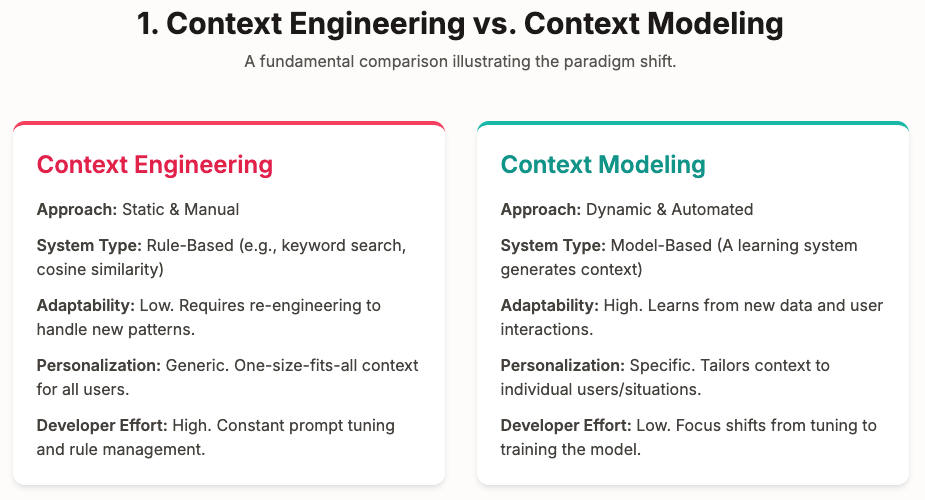
Andrej Karpathy, a prominent voice in the AI community, recently brought the term “Context Engineering” to the forefront. It describes the intricate art of manually crafting prompts and data to guide Large Language Models. While the concept is gaining significant attention, I believe it points us in the wrong direction.

The future of personal AI isn’t about endlessly engineering context, but requires a radical shift to what I call ‘context modeling.’

This isn’t just semantics—it’s the difference between a temporary patch and a real solution.

The Limitations of Current RAG Systems

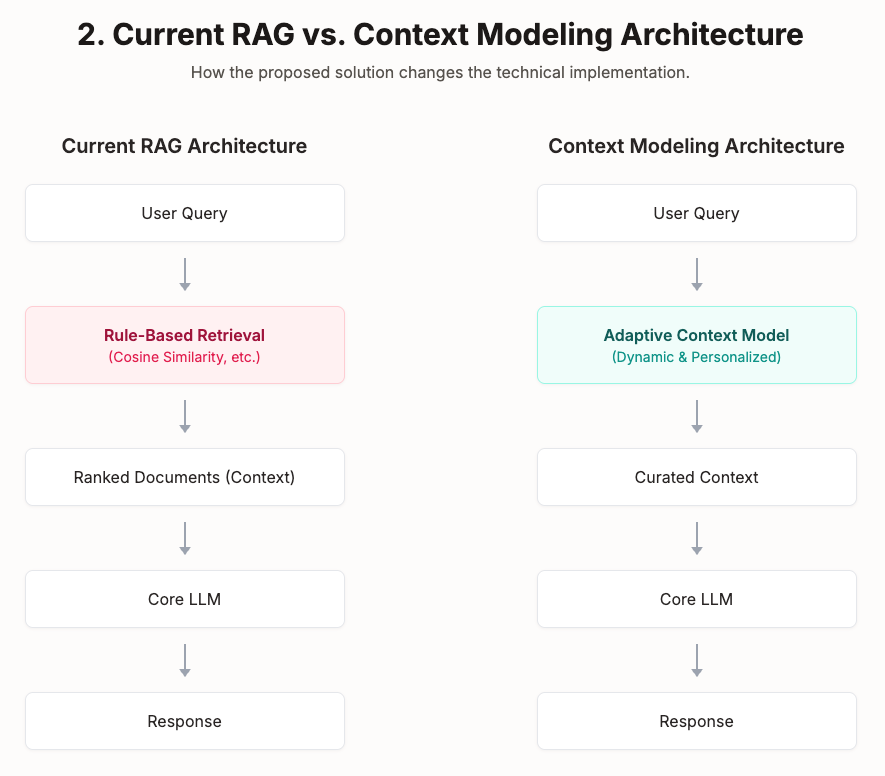
Today’s Retrieval-Augmented Generation (RAG) systems follow a relatively straightforward paradigm. They retrieve relevant information using rule-based systems—typically employing cosine similarity to find the top-k most relevant results—and then present this context to a large language model for processing. While this approach has proven effective in many scenarios, it suffers from significant limitations.

Think of current LLMs as exceptionally intelligent but stubborn team members. They excel at processing whatever information is presented to them, but they interpret data through their own fixed worldview. As these models become larger and more complex, they also become increasingly “frozen” in their approaches, making it difficult for developers to influence their internal decision-making processes.

From Engineering to Modeling: A Paradigm Shift

The conventional approach of context engineering focuses on creating more sophisticated rules and algorithms to manage context retrieval. However, this misses a crucial opportunity. Instead of simply engineering better rules, we need to move toward context modeling—a dynamic, adaptive system that generates specialized context based on the current situation.

Context modeling introduces a personalized model that works alongside the main LLM, serving as an intelligent intermediary that understands both the user’s needs and the optimal way to present information to the large language model. This approach recognizes that effective AI systems require more than just powerful models; they need intelligent context curation.

Learning from Recommendation Systems

The architecture for context modeling draws inspiration from the well-established two-stage recommendation systems that power many of today’s most successful platforms. These systems consist of:

  • Retrieval Stage: A fast, efficient system that processes large amounts of data with a focus on recall and speed.
  • Ranking Stage: A more sophisticated system that focuses on accuracy, distilling signal from noise to produce the best results.

RAG systems fundamentally mirror this architecture, with one key difference: they replace the traditional ranking component with large language models. This substitution enables RAG systems to solve open-domain problems through natural language interfaces, moving beyond the limited ranking problems that traditional recommendation systems address.

However, current RAG implementations have largely overlooked the potential for model-based retrieval in the first stage. While the industry has extensively explored rule-based retrieval systems, the opportunity for intelligent, adaptive context modeling remains largely untapped.

The Context Modeling Solution

Context modeling addresses this gap by introducing a specialized model dedicated to generating context dynamically. This model doesn’t need to be large or computationally expensive—it can be a focused, specialized system trained on relevant data that understands the specific domain and user needs.

The key advantages of context modeling include:

  • Adaptability: Unlike rule-based systems, context models can learn and adapt to new patterns and user behaviors over time.
  • Personalization: These models can be trained on user-specific data, creating truly personalized AI experiences that understand individual contexts and preferences.
  • Efficiency: By using smaller, specialized models for context generation, the system maintains efficiency while providing more intelligent context curation.
  • Developer Control: Context modeling provides agent developers with a trainable component they can influence and improve, creating opportunities for continuous learning and optimization.

The Ideal Architecture: Speed and Specialization

For context modeling to be viable, it must satisfy one critical requirement: speed. The latency of the core LLM is already a significant bottleneck in user experience.

Right now, the main workaround is streaming the response. However, the latency to the first token cannot be mitigated by streaming. The end-to-end latency of the retrieval model contributes to the latency of the first token. Any context modeling system must be exceptionally fast to avoid compounding this delay.

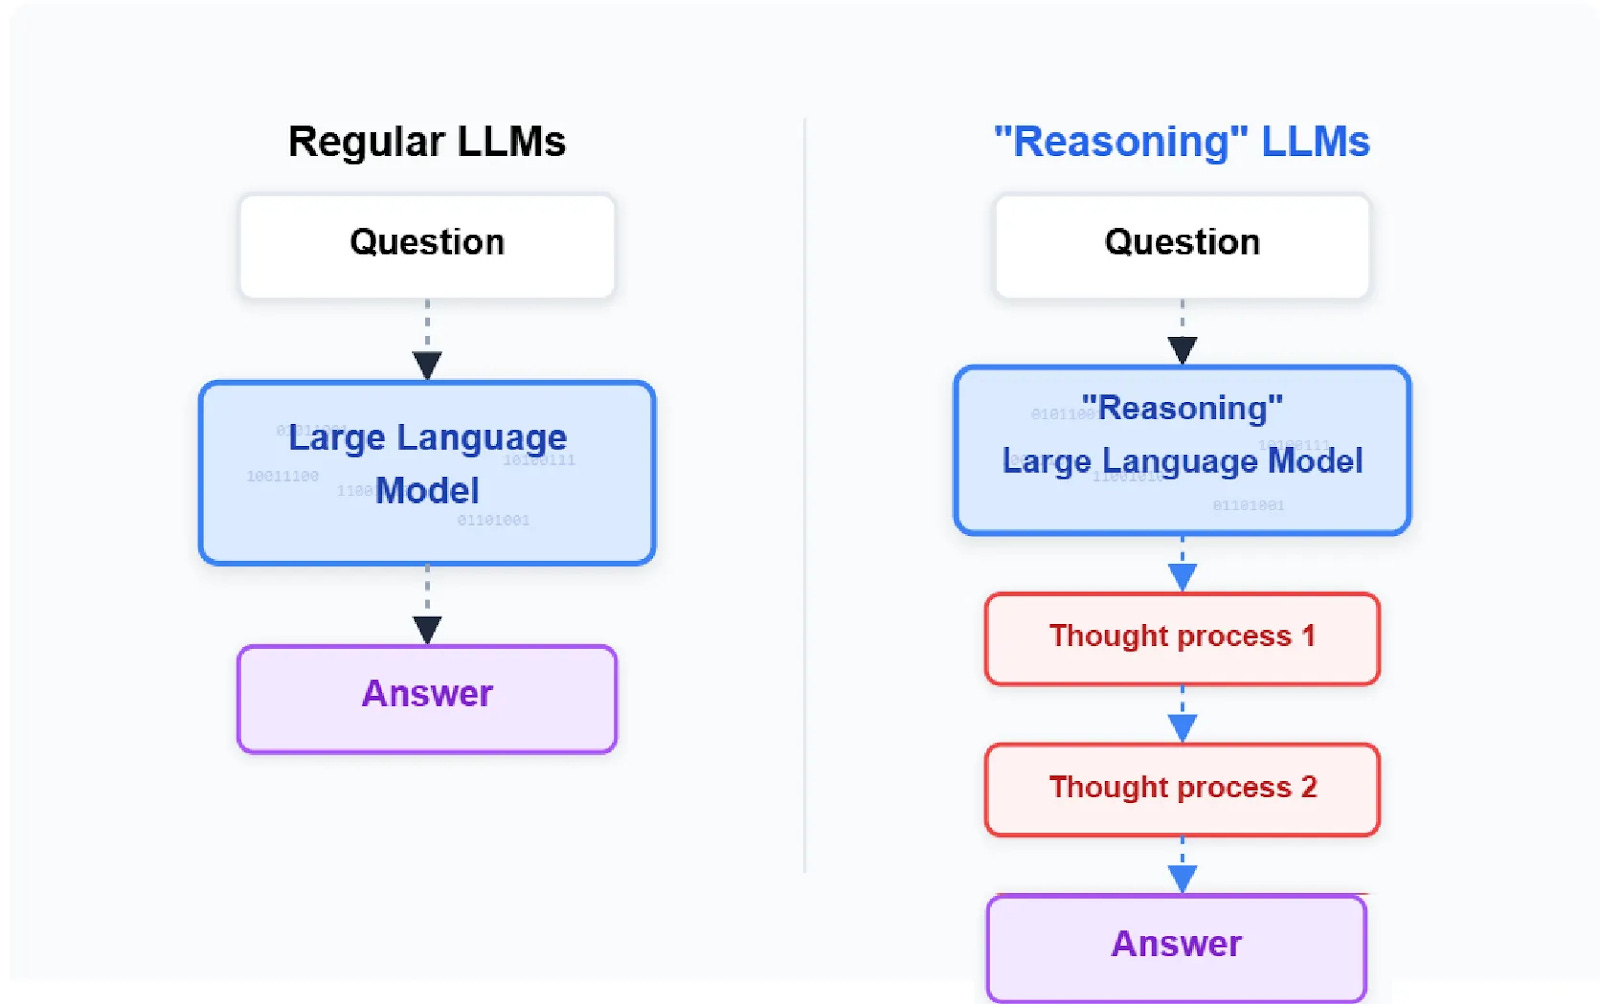
This brings us to the concept of “thinking” models, which use their own internal mechanisms to retrieve and reason over context before generating a final answer. In a sense, these models perform a specialized form of context modeling. However, their primary challenge is that this “thinking” process is slow and computationally expensive.

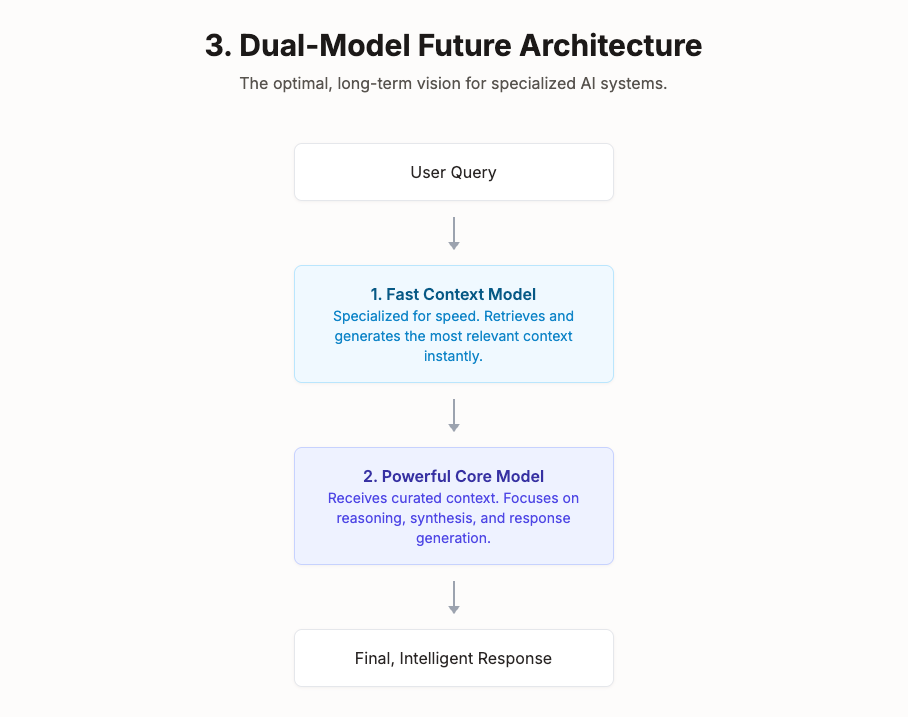
I argue that these monolithic “thinking” models are an intermediate step. The optimal, long-term architecture will decouple the two primary tasks. It will feature two distinct models working in tandem, mirroring the two-stage systems that have been so successful in recommendations:

  1. A Fast Context Model: A highly optimized, specialized model dedicated solely to retrieving and generating the most relevant context at incredible speed.
  2. A Powerful Core Model: The large language model that receives this curated context and focuses on the complex task of reasoning, synthesis, and final response generation.

This dual-model approach allows for specialization, where each component can be optimized for its specific task, delivering both speed and intelligence without compromise.

The Infrastructure Opportunity

Context modeling represents a common infrastructure need across the AI industry. As more organizations deploy RAG systems and AI agents, the demand for sophisticated context management will only grow. This presents an opportunity to build foundational infrastructure that can support a wide range of applications and use cases.

The development of context modeling systems requires expertise in both machine learning and system design, combining the lessons learned from recommendation systems with the unique challenges of natural language processing and generation.

Looking Forward

The future of personalized AI lies not in building ever-larger language models, but in creating intelligent systems that can effectively collaborate with these powerful but inflexible models. Context modeling represents a crucial step toward this future, enabling AI systems that are both powerful and adaptable.

As we move forward, the organizations that successfully implement context modeling will have a significant advantage in creating AI systems that truly understand and serve their users. The shift from context engineering to context modeling isn’t just a technical evolution—it’s a fundamental reimagining of how we build intelligent systems that can adapt and personalize at scale.

The question isn’t whether context modeling will become the standard approach, but how quickly the industry will recognize its potential and begin building the infrastructure to support it. The future of personalized AI depends on our ability to move beyond static rules and embrace dynamic, intelligent context generation.

Questions or feedback? I’d love to hear your thoughts.

Want more insights? Follow me:

🎙️ Founder Interviews: https://www.youtube.com/@FounderCoHo
Conversations with successful founders and leaders.

🚀 My Journey: https://www.youtube.com/@jingconan
Building DeepVista from the ground up.

Categories
English

Think Wider: AI as Perspective Partners

Everyone’s obsessed with making AI reason deeper — train models to solve complex mathematics and master intricate proofs. But in this race for artificial intelligence, we’ve forgotten something fundamental about human intelligence – how we actually think and work with others.

Deep reasoning is important, but it’s only half the story. What if, instead of treating AI as tools to be prompted, we can engage with them as naturally as we do with brilliant colleagues – each bringing their unique perspective to the conversation? This isn’t just about making AI think deeper – it’s about unlocking its breadth of knowledge through better questions.

Asking good questions is harder than finding answers. Try this mental exercise: give yourself two minutes to write down ten meaningful questions about different topics. Hard, isn’t it? The difficulty lies in where to even begin. With regular problems, we at least have a starting point – a puzzle to solve, a goal to reach. But with questions, we’re creating the map before we know the territory. It’s not about finding the right path; it’s about imagining what paths might exist in the first place.

And this is where LLMs shine: they’re incredible brainstorming partners. Not just because they can process vast amounts of information, but because they can consider countless angles that might never occur to us. Humans are limited by our experiences and cognitive biases. LLMs don’t have these limitations. They can draw connections between seemingly unrelated concepts and suggest possibilities we might never have considered.

The challenge isn’t that LLMs lack knowledge – they have plenty. The real problem is that we don’t know how to extract it effectively. We initially thought prompt engineering was the magic key, but that turned out to be too simplistic. It works, but it feels mechanical and constrained. We don’t think about conversation frameworks or prompt strategies when chatting with friends. We just… talk.

What we need is AI that can match this natural fluidity of human conversation. Imagine an AI system that could seamlessly shift between different types of expertise, like a conversation with a renaissance polymath who can speak authoritatively about both quantum physics and Renaissance art. This isn’t just about role-playing – it’s about having access to different ways of thinking about problems.

Imagine an AI system that could seamlessly shift between different types of expertise, allowing you to converse with a diverse range of experts. For instance, you could discuss quantum physics with a renowned physicist like Albert Einstein, then transition to a conversation about Renaissance art with an art historian like Giorgio Vasari. This isn’t merely about role-playing; it’s about accessing diverse perspectives and specialized knowledge to enhance your understanding and problem-solving abilities.

I’ve started calling this concept “persona-driven discovery,” and I believe it could revolutionize how we learn and solve problems by acting as a catalyst for serendipity.

We’ve all had those magical moments in libraries where we stumble upon exactly the book we needed but weren’t looking for. These AI systems could create those moments deliberately, suggesting unexpected perspectives and prompting us to explore unfamiliar territories. It’s like having a brilliant friend who knows when to push you out of your intellectual comfort zone.

All of this points toward a future where AI tools aren’t just answering our questions but actively participating in our thinking process. They could help us prototype ideas faster, facilitate group brainstorming sessions, and create personalized learning experiences that adapt to our individual ways of thinking.

The real breakthrough will come when we stop thinking about these systems as tools and start thinking about them as thought partners. This shift isn’t just semantic – it’s fundamental to how we might solve problems in the future. Instead of asking an AI to complete a task, we might engage it in a genuine dialogue that helps us see our challenges from new angles.

The building blocks are already there: we have models that can process and generate human-like text, we have systems that can maintain context in conversations, and we’re developing better ways to keep AI knowledge current and relevant. 

There are still unsolved problems.  When we make AI systems more specialized (like training them to be history experts), they often lose their broader capabilities. It’s the same trade-off you get with human experts – deep knowledge in one area often comes at the cost of breadth. The trick will be creating systems that can maintain both depth and breadth, switching between different modes of thinking without losing their fundamental capabilities.

This is what role-aware AI systems could offer – not just rigid question-and-answer sessions, but fluid conversations where different perspectives emerge organically as needed. Each AI “participant” would bring their unique expertise and viewpoint while staying current with the latest developments in their field. They would build on each other’s insights, challenge assumptions, and help you see problems from angles you might never have considered on your own. The key isn’t just having access to different types of knowledge, but having them work together in a way that mirrors the natural give-and-take of human conversation.

The potential impact of this shift could be profound. Just as the internet changed how we access information, these AI thought partners could change how we process and use that information. They could help us break out of our mental ruts, see connections we might have missed, and approach problems from angles we might never have considered.

This is the future I’m excited about – not one where AI replaces human thinking, but one where it enhances and expands it in ways we’re just beginning to imagine.

BTW, this essay is written after a long brainstorming session with the Hachi of “Paul Graham”. You can check it here: https://go.hachizone.ai/pg-think-wider

Please message me at jing AT hachizone.ai if you have any feedback on this essay or Hachi in general.

Categories
English

Rethinking Digital Discovery: From Algorithms to Human Perspectives

In our quest to organize the world’s information, we’ve created two dominant systems: search engines and recommendation algorithms. Both promised to make discovery easier, yet each has introduced its own set of challenges. Let’s examine why these systems fall short and how we might find a better way forward.

The Consensus Trap of Search Engines

In 1998, Google revolutionized the internet with PageRank, an algorithm that organized information through collective wisdom. The premise was elegant: websites with more backlinks were probably more important and trustworthy. It was democracy in action – the internet voting on itself through links.

While this approach works beautifully for factual queries like “what is the speed of light,” it struggles with nuanced topics where diversity of perspective matters more than consensus. The very nature of PageRank creates a self-reinforcing cycle: popular sites become more visible, leading to more backlinks, leading to even greater visibility.

This system inadvertently flattens the richness of human knowledge into a popularity contest. It’s as if we’re asking the entire world to vote on the best restaurant in your neighborhood – the results might reflect broad appeal, but they’re unlikely to match your specific tastes or needs.

The Echo Chamber of Recommendation Systems

On the other side, we have recommendation systems that promise personalization but often trap us in what we call “rabbit holes.” These algorithms study our behavior and serve us more of what we’ve liked before, creating increasingly narrow feedback loops.

Start watching a few cooking videos, and suddenly your entire feed becomes culinary content. Click on a political article, and your recommendations quickly become an echo chamber of similar viewpoints. While this approach maximizes engagement, it does so at the cost of serendipity – those unexpected discoveries that broaden our horizons.

The problem isn’t just that these systems can be limiting; it’s that they operate as black boxes. Users have little understanding of why they’re seeing certain content and even less control over steering their discovery journey.

Looking Back to Move Forward

Interestingly, the solution to these modern challenges might lie in how we discovered information before these technologies existed. Think back to how we naturally sought out knowledge: through conversations with friends, colleagues, and mentors.

When we wanted to discover new books, we didn’t poll the entire world or rely on an algorithm to analyze our past reading habits. Instead, we talked to friends whose taste in literature we trusted. When we needed restaurant recommendations, we asked colleagues who shared our culinary preferences.

This system worked because:

  1. We understood exactly why we valued each person’s perspective
  2. We could actively choose whose recommendations to seek out
  3. Different friends offered different viewpoints, naturally creating diversity
  4. Serendipitous discoveries happened organically through conversation

The Power of Personal Perspective

What if we bring this human-centered approach to digital discovery? Imagine a system that doesn’t try to replace human judgment with algorithms, but instead helps you find and follow the curators whose perspectives you value.

This isn’t just personalization based on your past behavior – it’s about actively choosing whose lens you want to view the world through. A food critic might have thousands of followers, but you might prefer your friend’s hole-in-the-wall recommendations because they understand your particular palate.

The beauty of this approach is that it preserves what makes human curation special:

  • Natural serendipity through the diverse interests of your trusted curators
  • Full transparency about why you’re seeing certain content
  • Control over whose perspectives influence your discovery
  • The ability to step out of your comfort zone by following curators with different viewpoints

A New Path Forward

The future of information discovery isn’t about achieving perfect consensus through PageRank, nor is it about increasingly sophisticated recommendation algorithms. It’s about recognizing that people – with their unique perspectives, expertise, and ability to surprise us – are the ultimate curators of information.

By bringing the human element back to discovery, we can create a system that offers both personalization and serendipity, both efficiency and understanding. Most importantly, we can build a system that puts users back in control of their discovery journey.

The future of discovery isn’t about finding what algorithms think is best – it’s about connecting with the human perspectives that truly resonate with you.

Categories
English

Beyond the Hype: Three Lessons from a Startup Rollercoaster

My first startup journey was a rollercoaster – a wild ride that began with a spark of an idea.

Drawing from my experience at Google Brain, I had a strong instinct that combining human feedback using reinforcement learning would significantly improve the experience of LLMs in dialogue. I started to explore this idea to build an assistant for knowledge workers in 2021. My gut told me there was a big opportunity in the space, but I wasn’t sure when the mass market would recognize it. Later, it turned out that this was one of the fundamental ideas behind ChatGPT.

However, everyone said the space was tiny back then, and potential investors and peers saw little value in my concept. As a first-time founder, the unanimous skepticism I made me doubt my vision. I ended up wasting a lot of time and getting distracted by other directions.

I eventually pushed forward, though not fast enough. We launched in September of 2022, right before ChatGPT was released. When we launched, we were amazed by the positive feedback and delight we got from customers. However, within months, ChatGPT’s release completely transformed the landscape. Suddenly, customers began to have much higher expectations and hesitated to sign contracts.

It was obvious that we had to build more to make ourselves stand out. However, the process felt like a constant chase of whimsical hope. We tried to tackle different parts of our customers’ workflow. Customers told us they liked our AI capability but missed features they longed for from their existing vendors. We tried to build those, but existing incumbents would quickly add AI capabilities similar to ours, making our new solutions seem redundant.

I ended up starting a new startup in a completely different space. But I learned three crucial lessons from the first startup journey.

You need to trust your gut.

I wasted a precious year that could have helped us build a more defensible moat and establish ourselves as the market leader, better preparing us for when ChatGPT’s storm hit. A few months of lead time is not enough—you often need more. When everyone says your idea is impractical, it is the best time to build your competitive advantage. Innovation rarely comes from following the crowd. It emerges from the courage to pursue ideas that seem impossible—until they aren’t.

Unique insight means nothing without a defensible moat.

Consider your competitive moat early on. While talking to customers helps identify valuable problems to solve, it doesn’t guarantee that your solution will be the only one customers choose. You need to figure out why customers would pick your solution over alternatives.

Technology is not a silver bullet; it is actually a very poor moat because ideas diffuse naturally.

At the beginning, the only competitive advantage of a startup is the time you get because of the ignorance of big players. But you need to turn it into an actual moat — reasons why customers should use you, not other players. For B2B companies, the reason is often data or customer relationships. For B2C, the reason is often branding or better user experiences.

Plus, you need to make sure you have the resources to build your moat, which requires strategic planning if you are already in fierce competition. (Unfortunately, it often creates conflicts with the customer-first culture in B2B).

Don’t be afraid to restart from zero.

If you’re facing strong headwinds and haven’t had time to build a moat, take a step back. Rethink what other valuable problems exist that you believe in but others haven’t yet recognized.

My story isn’t unique – it’s a microcosm of the startup ecosystem. Innovation isn’t about having the perfect idea from day one. It’s about resilience, adaptability, and the willingness to transform setbacks into insights.

Ultimately, I started a new venture in a different sector, carrying these lessons like a compass. Each “failure” was actually a sophisticated learning experience, and helped me transform into a true entrepreneur.

Categories
中文

2024: 关于中美创业生态的思考

借着我筹备新创业项目的契机, 过去三个星期我去中国跑了好几个城市,和很多朋友进行了深入交流,也有非常多的感悟和收获。这些也希望和大家分享一下。

这次创业之初为什么要去中国考察?我的职业和创业经历都在美国,上次创业基本上仅仅依托美国的创业生态系统,很少利用到作为华人的优势。但是我周围最优秀的朋友和师长都告诉我:一个优秀的企业Day 1就要是一个国际化的企业。如何能够整合全球的资源是一个成功企业的必要要素。尤其是我的华科师兄姚欣帮我系统的梳理了中国国内创业生态系统相比美国的生态系统的三大优势和劣势。1)产品思维。2)供应链优势,3)人才红利 。我在过去一年的创业过程中见到了很多非常好的中国出海企业, 对这些优势已经有了一定的了解。但是耳听为虚,眼见为实。这次回国也是希望能够更加系统的了解和观察。思考如何利用好这三大优势帮助构建下一次创业的护城河。

我先聊聊产品思维。上一波移动互联网对中国的影响力远远超过了美国。在这个过程中锤炼出了一大批非常优秀的产品人。通常来说对于国内产品人对产品的使用场景想得特别的细致。比如对比一下谷歌和百度的地图APP。谷歌地图是一个非常简洁的APP。用户选择目的地,获得导航信息,除此以外没有其他的设计。相比之下,百度地图至少就包括了 1)推荐车道的指示,2)语音包,2)一键打车。4)路况实时提示。5)违规拍照提示。这还只是一小部分,基本上常见的痛点都有一整套完整的功能设计。而且这个并非个例,比如滴滴和Uber相比对场景想得也精细得多。同时国内还需要大量美国完全没有出现的应用,比如本地生活这个门类在美国就完全没有出现。

我在回国之初我们项目只是想到了这些点 1)要做个性化大模型,2)首先切入陪伴,3)可能包含一些硬件。但是国内的一些优秀产品人聊过之后我意识到我的想法显然是过于粗了。至少我需要有这些问题的答案:产品形态是什么?用户为什么需要做陪伴?获得的价值是什么,什么样的产品功能能够体现这个价值?谁是获得主要价值的人?这个是给我的一个系统性的启发,让我开始仔细的思考产品的场景。

接着说说供应链优势。这次对我印象非常深刻的一点就是深圳的硬件生态系统在全球范围是遥遥领先的。在美国做硬件项目的难度极高,里面只要还有一点硬件元素基本难倒了99.999%的创业者。但是在深圳,具有相当完备的硬件生态的完善,使得硬件创业的门槛大幅降低。比如我短短几天至少找到三家可以大致生产我所需要硬件的供应商。而且大家对合作都非常的开放。

当然我还是感受到虽然深圳的硬件系统发达,在创业的起始阶段,碰硬件是一个非常危险的事情。主要两个问题。

  1. 虽然深圳硬件的生态系统很发达,但是如果需要真正用上深圳的供应链优势,你必须对硬件指标有了很明确的需求。一旦出现错误,对于时间和资金的浪费是创业公司难以承受的。
  2. 库存对于资金的消耗是非常大的,容易引发资金链断裂。

做硬件比较适合公司已经找到了产品的Product market fit,需要进一步稳固护城河和第二增长极的时刻,比如是B轮之后。

最后说说人才红利。在过去十几年互联网的发展也积累了大量的人才。而且随着过去两年的互联网的形势变化,和人民币对于美元的贬值,人才成本普遍下降了30%以上。使得在国内进行招聘变得非常的有吸引力。总的来说,国内一线城市的用工成本大概是旧金山湾区的一半左右。二线城市(比如成都武汉)是一线城市的70%左右。中国本身其实也分为几个小的创业生态系统,各个系统的人才还是不一样。一线城市里面,北京在互联网人才集中程度上具有明显优势。上海人的产品经理(尤其是在本地生活领域)特别强,深圳的硬件人才非常的多。二线城市里面我只去了成都和武汉。成都的软件人才是明显多于武汉。但是武汉有很多光学和硬件的人才,相对比较均衡。

另外我的感受是从人才密度和环境来说,国内二线城市和一线城市的差距要远远大于一线城市和硅谷的差距。尤其是AI方向的人才,二线城市非常的缺乏。一线城市在人才的密度,人的信息上来说和美国基本比较接近的。但是二线城市还是信息流通不畅。很多在一线城市大多已经比较常见的信息,在二线城市基本上还是很少人知道。相对来说,如果仅仅是比较传统的软件开发或者测试,放在二线城市没有问题。但是如果需要非常快速更新的领域(比如AI岗位),还是要放在硅谷或者一线城市。加拿大也是不错的选项,成本略高于国内一线城市,但是和硅谷没有时差,沟通起来容易很多。

另外,国内的APP开发已经达到了流水线化生产的地步。基本上APP开发的速度可以达到美国类似团队的两倍以上。如果能够合理的利用,这是一个非常大的优势。

说了这么多的优势,我也想说说我看到了需要注意的地方:

  1. 一是国内对于diversity较不看重。这个导致了生态系统偏向同质化竞争, 创新性不足。如果有大量的国内团队,如何保证团队的diversity和创新性是一个需要注意的事情。
  2. 二是中国的很多经验不能直接照搬到美国。前几年有一阵子Copy From China的热潮,有很多公司把国内的支付和本地生活的项目照搬到美国 ,但是没有特别成功的。这次我也对这个问题有了系统的反思。中国是一个单一文化国家,全中国14亿人的消费习惯都比较接近。而且由于竞争压力大,很多产品设计是对中国消费者的习惯过度拟合的。与此相比美国不是一个单一文化文化国家。和中国文化类似的人群只有600万左右的华裔和2000万左右的亚裔。每个人群具有非常明显不同的消费习惯。仅仅照搬中国的产品形态会对于华人群体形成过拟合,使得产品在切入美国其他族裔人群的时候遇见困难。但是美国的华裔的人口只相当于中国的一个地级市,仅仅服务这个人群又不足以支撑一个大型的公司。

中国的消费商业模式向美国溢出是一个大概率事件。但是并不是所以消费业务形态都会适合。 在美国要做好消费类的业务,必须打的是人类的普遍感情。不能够对于具体的人群过分的优化。什么事普遍情感?迪士尼的产品其实主打的就是一个非常朴素的人类普遍感情 — 真善美。这是它为什么能够迈向全球的原因。中国的亲子陪伴类业务基本上都完全转向了教育 — 比如课本绘本或者学习机之类。这个如果直接照搬是不行的。华人文化对于学习是非常的重视的,但其他族裔对于教育的关注的程度要远低于华人。如果针对教育过分优化,会难以跳脱华人群体。但是害怕孤单是一个普遍的情感,从陪伴这个角度切入会是更好的选择。

回过头来说这次的考察的思考。我觉得整合全球的资源是不仅是一个优秀企业家的机会而且也是一种责任。过去的几年似乎全球化碰到了一些波折,但是我觉得全球融合的大趋势是不会发生改变的 — 不论是大量的优秀中国公司出海,还是更多的外国企业整合中国的资源。无论文化或者族裔,人对于美好生活的向往是共通的,只有全球资源一体化,才能够更加有效的创造出优质的产品,为每一个人创造更加美好的生活。

link of this post: https://s.jing.me/2024-cn-us-startup-ecosystem

Categories
中文

从零到一:大模型技术的创造史

虽然大模型是在OpenAI推出了ChatGPT之后进入公众视野的,但是在ChatGPT之前大模型技术已经经历了很长一段时间的演化。我从2014年到2019年在谷歌工作,大模型的许多关键技术是在这段时间在谷歌大脑成熟的。整个技术的成型不是一蹴而就,而是由许多优秀的研究者和工程师接力完成。我有幸参与其中,作为一个亲历这个过程的人,这里希望记录一下这段经历。让大家了解一下这项划时代技术从零到一时期的一些故事。

大模型的开发不仅需要强大的计算能力,还需要解决于三个关键问题:架构、训练算法和数据。因为搜索引擎本质就是用自然语言进行互联网数据的查询,谷歌一直在自然语言处理方向的研究上面重金投入,最终逐渐解决了了这三个问题。

首先是架构。谷歌大脑一个很重要的任务是为谷歌的翻译任务提供模型支持。语言本身就是一个序列,所以很自然大家就开开始使用一种称为序列模型(Sequence Models)的神经网络来做这个。与上一代的卷积神经网(CNN)相比,序列模型是专门用于处理序列数据的。每一层的输出又称为下次迭代的输入。这样就可以处理很长的序列。

谷歌翻译是支持多种语言的相互翻译的,所以需要有一种架构可以非常容易扩展语言而不需要重新训练。从直观上来说,一种语言不过是为了表达特定含义的符号,翻译的本质就是使用不同的符号系统来表示同一个含义。于是大家考虑到如果能够用一个序列模型提取一种语言要表达的含义(编码器encoder),然后在用另外一个序列模型将将之转化成为另一种语言的符号(解码器decoder)。这样encoder-decoder模型架构就出现了。

Encoder-decoder模型架构刚刚出现(2014年左右)的时候效果不好,主要问题就是序列模型(sequence model)很容易遗忘信息,一般只能记住几个上下词,这就是我们提到的context window limit滥觞。这种问题之前也已经有一种方法解决,(LSTM, 长短时记忆模型)。LSTM效果不错,但是特别复杂,很难写。所以大家一直在寻在更加简化的架构。

Transformer架构(变压器架构)就是在这个背景下面诞生的 (2017年)。比起LSTM来说,Transformer架构简单很多,效果也非常的好。后来所有的大模型都是基于这个架构。Transformer的八位作者后来都离开了谷歌,几乎每个人都创立了一个独角兽公司,这就是所谓的“Transformer八子”。 Transformer架构刚刚出来的时候并没有引起大家的注意。主要是这样的架构在当时非常的难以训练,只有少数的人可以使用。

第二个部分是训练算法。2013年左右时候,谷歌发明了词嵌入技术(Word Embedding或者 Word2Vec)。这个技术能够把一个单词映射成为向量。如果两个词在语义上面比较接近,那么他们在向量空间的距离也会比较接近。词嵌入技术被首先用到了谷歌的搜索系统和广告机器学习系统里面作为特征,带来了很大的提升。但是很快大家发现了词嵌入技术存在一些问题。自然语言里面的词都具有多义性。同样的词随着它所处的上下文会具有完全不同的语义。

如何能够生成一个能够考虑上下文的词嵌入呢? 这个时候大家考虑到可以将一串词序列顺序的处理。如果从前往后扫一遍就可以知道上文,如果从后往前扫一遍就可以知道下文。这样上下文就都有了。这种考虑上下文的思路就演进成为了BERT(双向变压器表征编码器, 2018年)。

BERT这种双向的特点和后来OpenAI的GPT只是从前往后的范式稍有不同,但是原理都是一样。BERT最大的优点就是特别适合生成词嵌入(Embedding)。当时BERT的词嵌入用到谷歌的搜索广告系统里面让产生了1%的营收增长。谷歌每年大概2000亿美金的收入,光这一项改进,就是一年20亿美金的收入。BERT的出现也直接催生了谷歌的TPU项目。

BERT论文一个重大的贡献是让预训练-微调范式发扬光大了。这个范式其实在谷歌内部很早就开始有了。主要是谷歌研究部门是一种混合制的研究部门。既有人做基础模型研究,也有人(Applied Scientist)到各个部门去做落地。最开始每个部门的模型都是从头训练。但是随着模型的规模变大,对训练资源的要求越来越高。而且基础研究的人对于各个部门的业务也不是十分了解。这个时候如果负责基础研究的人能够做一个预训练的模型。各个应用的人再依据各自的业务问题做微调。会起到事半功倍的效果。

而且由于将所有的训练资源汇聚到一起,预训练模型可以做的很大。BERT是第一个将预训练模型发布到谷歌以外的团队。而且当时他们除了模型权重,也一并开源了模型代码。掀起了一波自然语言处理(NLP)热潮。著名的HuggingFace其实最开始就是BERT的一个PyTorch开源实现。

第三个部分是数据。预训练大模型需要大量的数据。传统的机器学习训练都是通过监督学习,需要大量的文本和标注。文本这个事情好说,英文里面有维基百科,里面有大量的文本,维基百科本身是非营利性组织,而且谷歌是维基百科的最大赞助商,获取数据没有什么太大的难度。但是标注需要人工做,欧美的标注成本很高,非常的不实际。半监督学习(Semi-Supervised Learning)就是在这个时候诞生的。半监督学习利用某种规则可以自动生成标注。比如说BERT从一段文本里面随机挖掉一个词,然后让模型来预测这个词。这个原理其实和我们人做完形填空的原理是一样的。

随着BERT的完善,谷歌内部开始基于这个能力做很多应用。很重要的就是多轮对话式推荐(Conversational Recommender)。传统的推荐系统是基于排序的,但是多轮对话式推荐是基于自然语言处理的,并且利用强化学习进行对齐。其实这已经就是后来ChatGPT的原理了。而且当时已经达到了类似ChatGPT的效果。但是谷歌对外发布的一些产品因为一些偏见多样化问题招致美国主流媒体的抨击,这使得谷歌研究院高层对于大模型方向的支持开始犹豫起来。同时谷歌内部模型落地的时候遇到了强大的阻力。因为这个是对于已有业务的一种颠覆式创新。但是在谷歌内部业务线的负责人或是无法看清这个趋势或是担心带来的冲击,不愿意引入,导致除了在YouTube取得一些成绩外其他的落地项目全部折戟。多方原因导致很多优秀人才流散,很多人后来或加入了OpenAI或自行创业继续这一事业。

起初OpenAI并不是专注于大模型的,但是在2019年谷歌内部动荡之际,OpenAI扛起了大模型的大旗。他们在谷歌的工作基础上推陈出新,专注于模型的泛化和Zero-Shot learning — 也就是用户不需要微调模型,只需要一些提示词(Prompt)就可以在多个领域达到相当程度可用的程度。事实证明,这个策略是非常成功的。因为大多数开发者其实并不具备微调能力。Prompt Engineering进一步降低了大模型的使用门槛,让人人都可以用大模型。

整个大模型发展的过程绝非是事前规划好的,而是大家在好奇心的驱动下不断摸着石头过河,最终趟出了道路。科技创新虽然不能被规划,但是是可以孕育的。只要有合适的创新环境,就会不断有新的技术涌现。当时的谷歌大脑和如今的OpenAI都是一些共同的特点:高密度的人才,充分的自由,海量的资源。这是这些地方能够孕育革命性技术,不断拓展科技边界的原因。

Categories
English

How 500 Lines of Code Challenged a $500M AI Giant, and What Moats GenAI Startups Should Have

Recently, there’s been an interesting development in the big model industry. Perplexity AI, a hot big model company in Silicon Valley, completed a financing round two months ago, valuing it at over $500 million. However, using Lepton AI’s middleware, Lepton’s co-founder Jiayang Qing managed to create an open-source version with just 500 lines of code over a weekend, sparking a heated discussion in the industry. The related demo on GitHub quickly garnered five thousand stars in just a few days. This incident reflects a broader trend, and I’ll analyze it based on my own year and a half of entrepreneurial experience.

Currently, big model companies can be categorized into three types:

  • Base model companies, which primarily provide big model capabilities. This area requires significant capital and resources are highly concentrated among leading companies and giants.
  • Middleware companies, which offer middleware between big models and applications. Jiayang Qing’s Lepton AI falls into this category.
  • Application-layer companies, which directly provide consumer-facing applications. These can further be divided into platform-type application companies, like Perplexity AI, and vertical application companies focusing on niche markets, such as Harvey AI, which recently completed financing for its legal application.

The incident with Perplexity AI and Lepton AI highlights a pain point for application-layer companies — high competitive pressure with insufficient moats. For instance, Perplexity, which aims to solve general information search problems, faces challenges from four fronts: pressure from giants like Google, competition from vertical knowledge applications like Harvey, market encroachment from other knowledge service companies, and disruptions from middleware companies like Lepton AI. Vertical application companies face slightly less pressure, but they still confront these four forces and have a smaller market size, resulting in fewer resources.

So, what can be done? Many entrepreneurs believe that accumulating proprietary data can create a sufficient moat. This is very sensible, but it presupposes a systematic methodology for acquiring proprietary data. Here, I propose a methodology: using contrarian insights to gain a time advantage, leveraging the founder’s personal strengths for breakthroughs, and focusing on data-first products or operational capabilities.

First, contrarian insights, or insights not commonly understood, are essential. Entrepreneurs must find less trodden paths to build their core competitive advantage with minimal resources. What was once a contrarian insight can become common knowledge, such as the combination of big models with chat interfaces, which was novel before ChatGPT but is now common.

Second, the founder’s personal advantage is crucial. While contrarian insights offer temporary protection, they quickly become common knowledge once proven useful. Here, a deep understanding of user pain points in vertical applications can be a personal advantage. For example, one of Harvey’s co-founders was a lawyer. Even if a team doesn’t have a co-founder from a specific industry, previous experiences that can be leveraged as industry advantages are valuable.

Finally, building a data-first product or operational capability is key. The founder’s personal advantage must be systematized to sustain. There are two strategies:

  • Product-driven: The founder uses their deep understanding of user needs to design a product that naturally accumulates high-quality data, enhancing the product experience and creating a flywheel effect.
  • Operation-driven: The founder uses their resources and experience to build an operational system that continually acquires proprietary data, making operations or sales more efficient and faster.

The former suits products focused on Product-led Growth (PLG), while the latter suits those driven by Sales-led Growth (SLG). Both must prioritize data. If product-driven, each feature should contribute to data accumulation. If operation-driven, operations should focus on data, not just revenue or other metrics.

Returning to Perplexity’s case, Jiayang Qing could replicate Perplexity’s main functions over a weekend but not its data accumulation. As a middleware company, Lepton likely doesn’t intend this as a core strategy. However, many new application startups may use this to challenge Perplexity further. Whether Perplexity can withstand this depends on its ability to build a moat with proprietary data.